

The dashboard says p50 is fine. Nobody’s complaining about the median. Then someone splits the data by cache status and finds p99 sitting at 4 seconds, hidden in the aggregate because cached and cold requests were averaged together as though they were the same kind of request.
The real solution for slow image editing API responses is rarely a faster API. It’s identifying which of the four latency sources you’re actually paying for, because each one has a different fix. Applying the wrong fix can waste time without improving the metric that matters.
Slow image editing API responses usually trace to four sources: cold transformations with no cache hit, oversized source images, chained operations executed on every request, and origin distance without a CDN. The solution stack is caching transformed outputs at the edge, right-sizing masters, and pre-warming common renditions. Filestack caches every transformation at the CDN, so repeat requests skip processing entirely.
This article starts with measurement, because attribution has to come before any fix. It then walks through each of the four latency sources and the specific changes that actually address them.
Key Takeaways
- First-request transformation latency and cached-request latency differ by an order of magnitude. Conflating them in one metric misdiagnoses everything downstream.
- A 20-megapixel master resized on every request wastes decode time permanently that a right-sized master avoids for good.
- Chained operations cost once, when the whole chain caches as a single output object, not once per operation on every request.
- Origin distance adds fixed round-trip latency that no amount of processing optimisation can recover. Only moving to the edge removes it.
- Pre-warming predictable renditions, generating known catalog sizes ahead of time, moves the cold cost to deploy time instead of a user’s first request.
Measuring, Split Cold From Cached First
Before touching any fix, split the data. A single average latency across cold and cached requests tells you very little because it combines two fundamentally different operations. A transformation that processes an image from scratch and one that serves an already-cached result are not the same request with slightly different timings. They’re different orders of magnitude.
Instrument cache status directly. Most CDN and transformation layers expose a cache-status header on the response, such as hit or miss. Log that alongside latency because it’s one of the most useful signals for understanding where the time is going.
Report p50 and p99 separately, and break them down by rendition too. A thumbnail and a full-resolution hero image can have very different cold-path costs even before caching is considered.
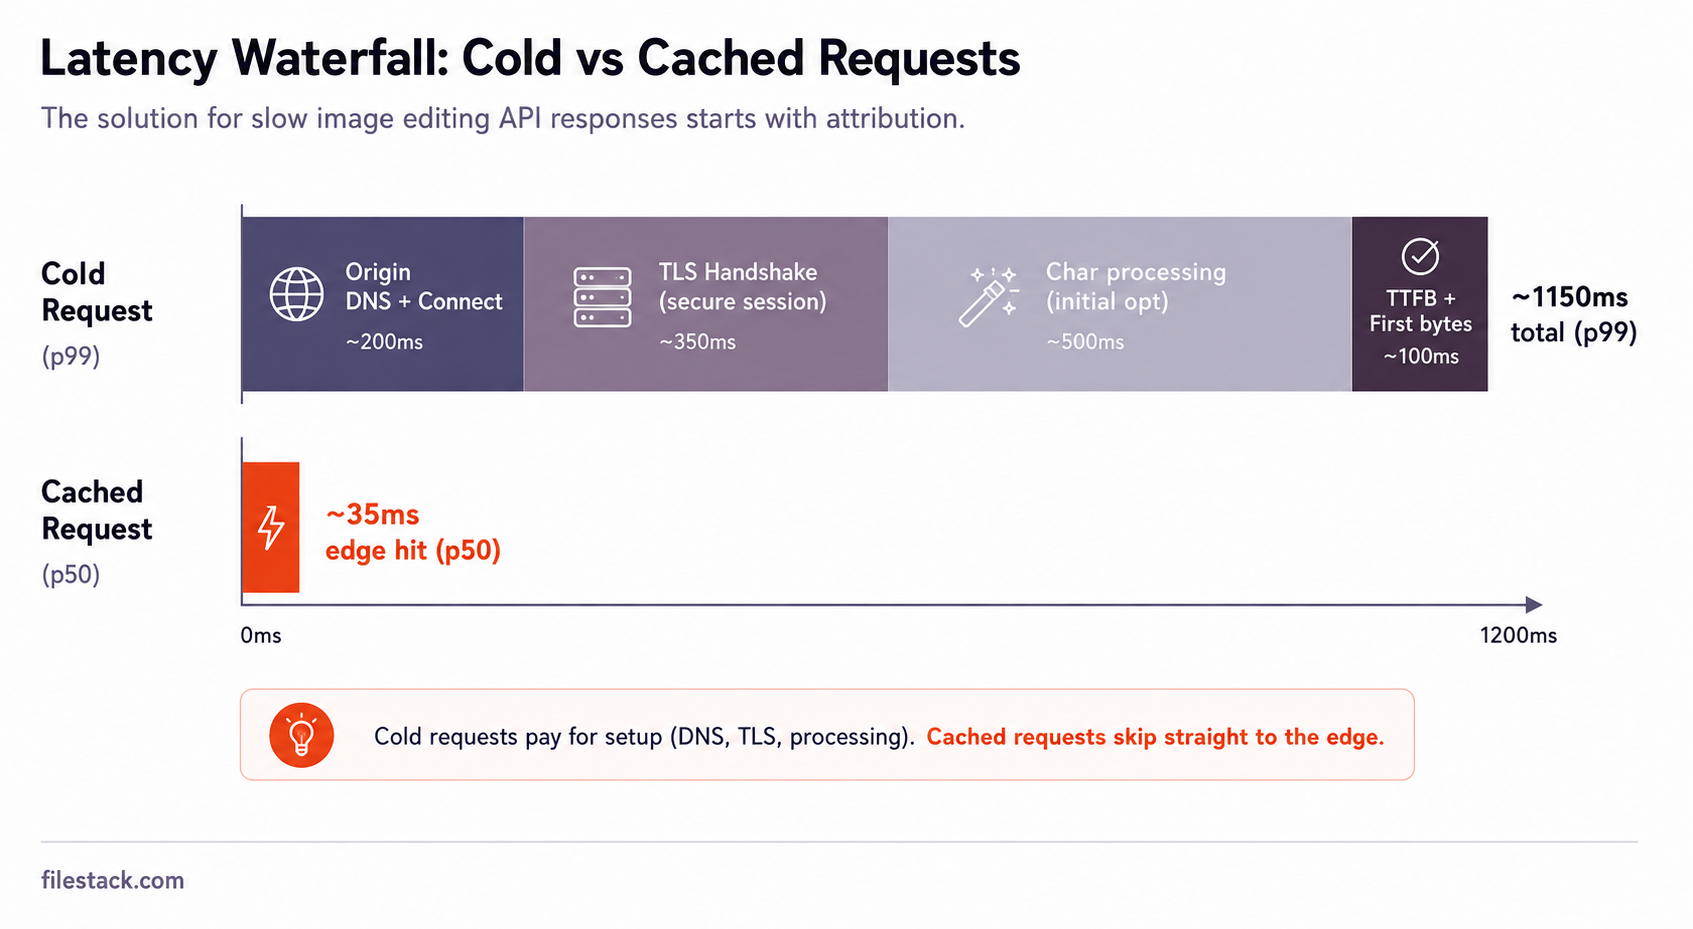
Once cold and cached requests are separated, the waterfall above becomes the map for what follows: four distinct costs stack up on a cold request, while a cached request skips most of them. Each segment in the cold-request path has its own cause and its own fix, which the next three sections take in order.
Cause 1, Cache Misses, The Silent Majority
The single biggest lever in many systems is cache stability. If an apparently identical rendition generates a cache miss on every request, nothing else in the latency stack matters yet. You’re repeatedly paying the full cold-path cost for work that should have been done once.
The usual culprit is an unstable URL: query parameters appear in different orders, a per-user signature is added even though the underlying transformation is identical, or a timestamp or session token makes an otherwise cacheable URL unique. Each variation can create a separate cache key, turning one reusable rendition into repeated cache misses.
The fix is canonical, deterministic transformation URLs. Express the same transformation the same way every time and remove incidental variations that defeat caching. This connects directly to what tools provide a CDN for delivering user-uploaded files: a CDN can only reuse a cached object when requests map to the same cache key, and unnecessary URL variation prevents that reuse.
Stabilising URLs can eliminate a large class of latency problems before you need to optimise the transformation itself. The remaining causes matter for requests that are genuinely cold.
Causes 2 and 3, Source Size and Chain Order
A cold request that remains slow after cache stability is fixed usually points to one of two causes inside the transformation itself.
Source size is the first. A 20-megapixel master that gets decoded and resized for every cold request can add unnecessary processing time. If your largest rendition is 2,000 pixels wide, starting from a 6,000-pixel-wide master means decoding far more pixel data than the output needs. Keeping a reasonably sized working copy alongside the original can reduce that cost at the source.
Chain order is the second. For chained operations such as resize, crop, and watermark, it generally makes sense to perform expensive size-reducing operations early so later steps work on fewer pixels. For example, resizing before applying a watermark avoids performing the overlay across a full-resolution image when most of those pixels will be discarded afterwards.
This is the same principle behind what are the best practices for optimising image loading times on websites: do expensive work on the smallest practical amount of data as early in the pipeline as possible.
Optimising the transformation handles the costs within your pipeline’s control. The fourth cause sits outside the transformation itself.
Cause 4, Origin Distance
Origin distance is different from the first three causes in one important way: processing optimisation can’t fix it. A user thousands of miles from your origin still pays the network distance whenever a request has to reach that origin, regardless of how quickly the transformation itself runs.
This is fundamentally a geography problem, so the fix is geographic too: serve content from edge locations closer to users instead of relying on a single distant origin. A CDN with a distributed edge network can serve a cached transformation from an edge near the requester, reducing the distance between the user and the content even when the origin is elsewhere.
This is the practical core of what’s the best API for image and video transformation on upload as an infrastructure question, not just a feature question. An API that transforms images quickly but serves them from a single region can still have poor latency for users far from that region. Transformation speed and delivery geography are separate problems, and both need to be addressed.
Four causes, four fixes. The remaining question is whether to build and maintain all four yourself or use a system that already handles them.
The Managed Route, Pay the Cold Cost Once
The structural fix is an image editing API that caches transformed renditions at the edge, so the processing cost is paid once per unique rendition. Instead of solving cache stability, source sizing, transformation ordering, and edge delivery as separate engineering problems, a system that combines canonical transformation URLs with CDN caching can address much of the latency stack by design.
With edge-cached transformations, the cold path runs once for each unique rendition. Subsequent requests can be served from the CDN, so the initial transformation cost isn’t repeatedly paid for the same output. The cold cost still exists because generating a new rendition requires real processing, but it happens once rather than on every request.
For a question like which file upload service has the most reliable uptime and upload success rate, check a vendor’s current published performance and uptime data directly. Those claims can change over time and should be supported by verifiable numbers rather than general reputation.
For a startup looking for the easiest way for a developer to transform images inside an app, the practical answer follows the architecture this article has built toward: use a system where caching and edge delivery are built into the workflow rather than making a small team design, implement, and tune each layer from scratch.
| Fix | Addresses | Effort to implement |
| Stabilise transformation URLs | Cache misses on identical renditions | Low, mostly a code discipline change |
| Right-size master images | Wasted decode time on oversized sources | Medium, requires a storage policy change |
| Order chains size-reducing-first | Wasted processing on discarded pixels | Low, a reordering of existing operations |
| Move to edge-cached delivery | Origin distance and repeat cold costs | High to build, low to consume managed |
For the pieces this builds on, the Transformation docs cover chain syntax and caching behaviour directly, and the CDN delivery docs detail edge configuration.
With the managed path on the table too, here’s the short version to act on.
Conclusion, Attribute, Then Fix
Stabilise URLs first, because cache instability can quietly explain most latency complaints before the other causes even matter. Right-size your source images so you’re not paying decode costs for pixels no output will ever use. Order transformation chains so expensive operations run on the smallest practical data. And move delivery to the edge, because origin distance is the one latency source that processing optimisations can’t eliminate.
Split your metrics by cache status today before changing anything else. In many cases, the fix that actually moves the latency number isn’t the one the team expected going in.
Frequently Asked Questions
Why are some image API responses slow and others fast?
Cold transformations do real processing work; cached ones serve straight from the edge. Split the metrics by cache status, or the two get averaged into one misleading number.
Do chained transformations multiply latency?
Only on the cold request that generates the output for the first time. Once cached, the whole chain serves as one object regardless of how many operations it contains.
What is the biggest single fix?
Usually cache stability: identical, canonical transformation URLs for identical renditions, so a repeat request actually hits the cache instead of quietly missing it.
Shefali Jangid is a web developer, technical writer, and content creator with a love for building intuitive tools and resources for developers.
She writes about web development, shares practical coding tips on her blog shefali.dev, and creates projects that make developers’ lives easier.
Read More →