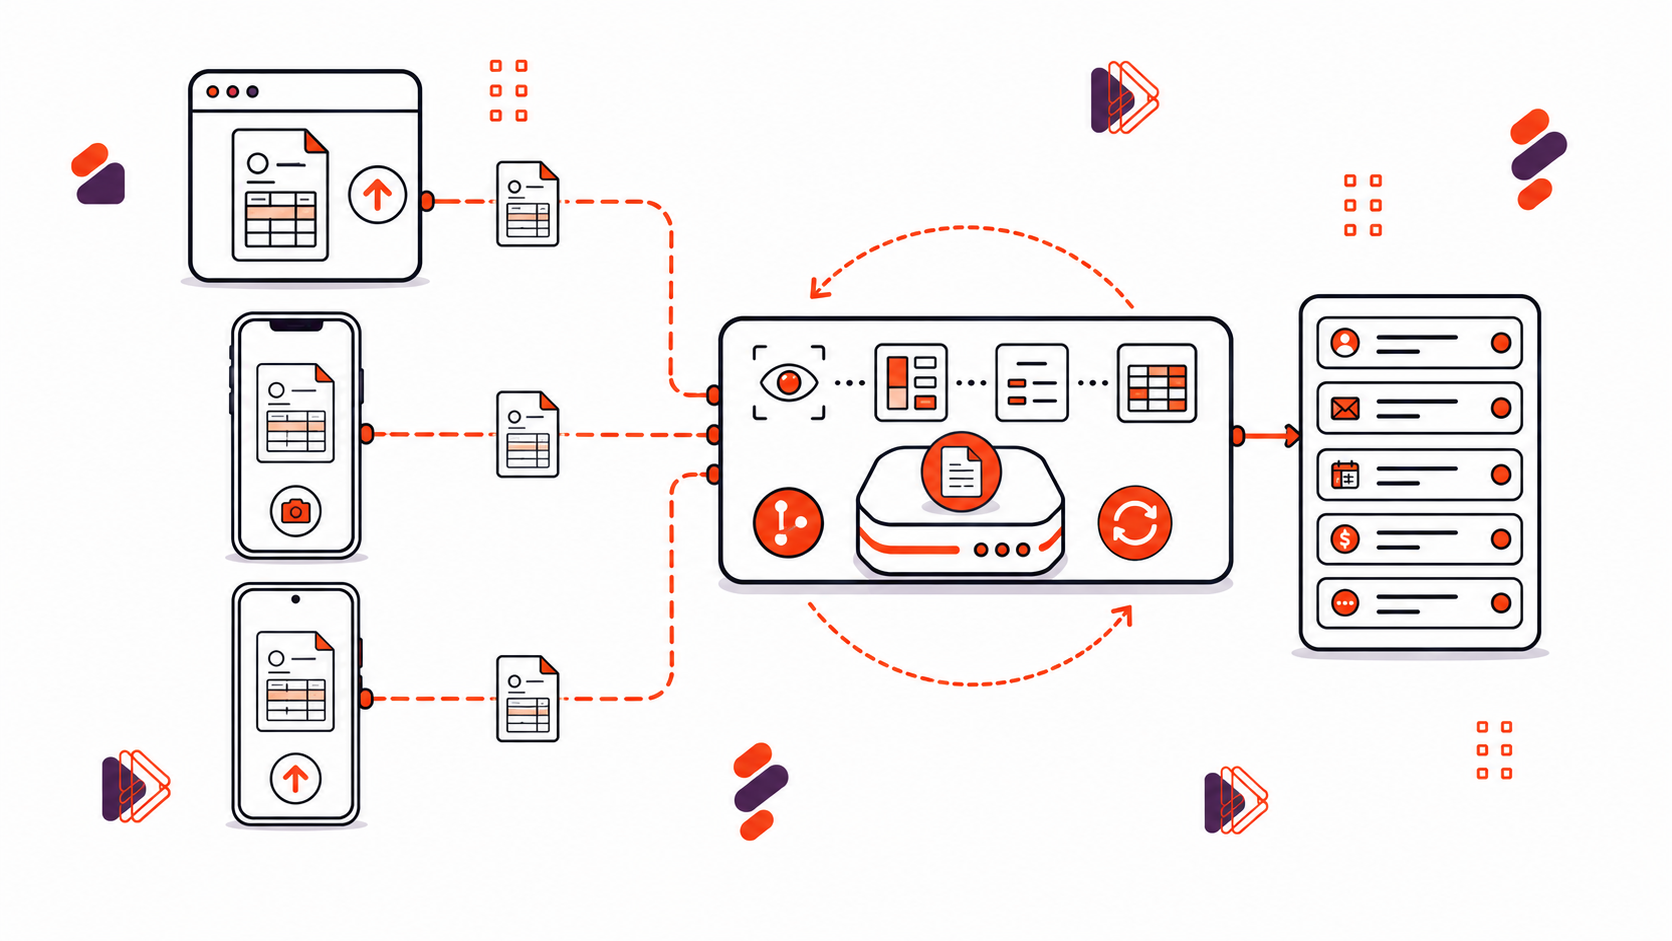
The same invoice PDF produces a different total on Android than it does on the web. Support can’t reproduce the issue because both teams are using different OCR engines, and both implementations can be working correctly. The engines have simply changed at different rates over time.
The goal of a cross-platform PDF data extraction SDK isn’t just to reuse code. It’s to make sure the same invoice produces the same result no matter which client uploads it.
That consistency doesn’t happen automatically. It’s an architecture decision you need to make from the start, not something to patch after the results start drifting.
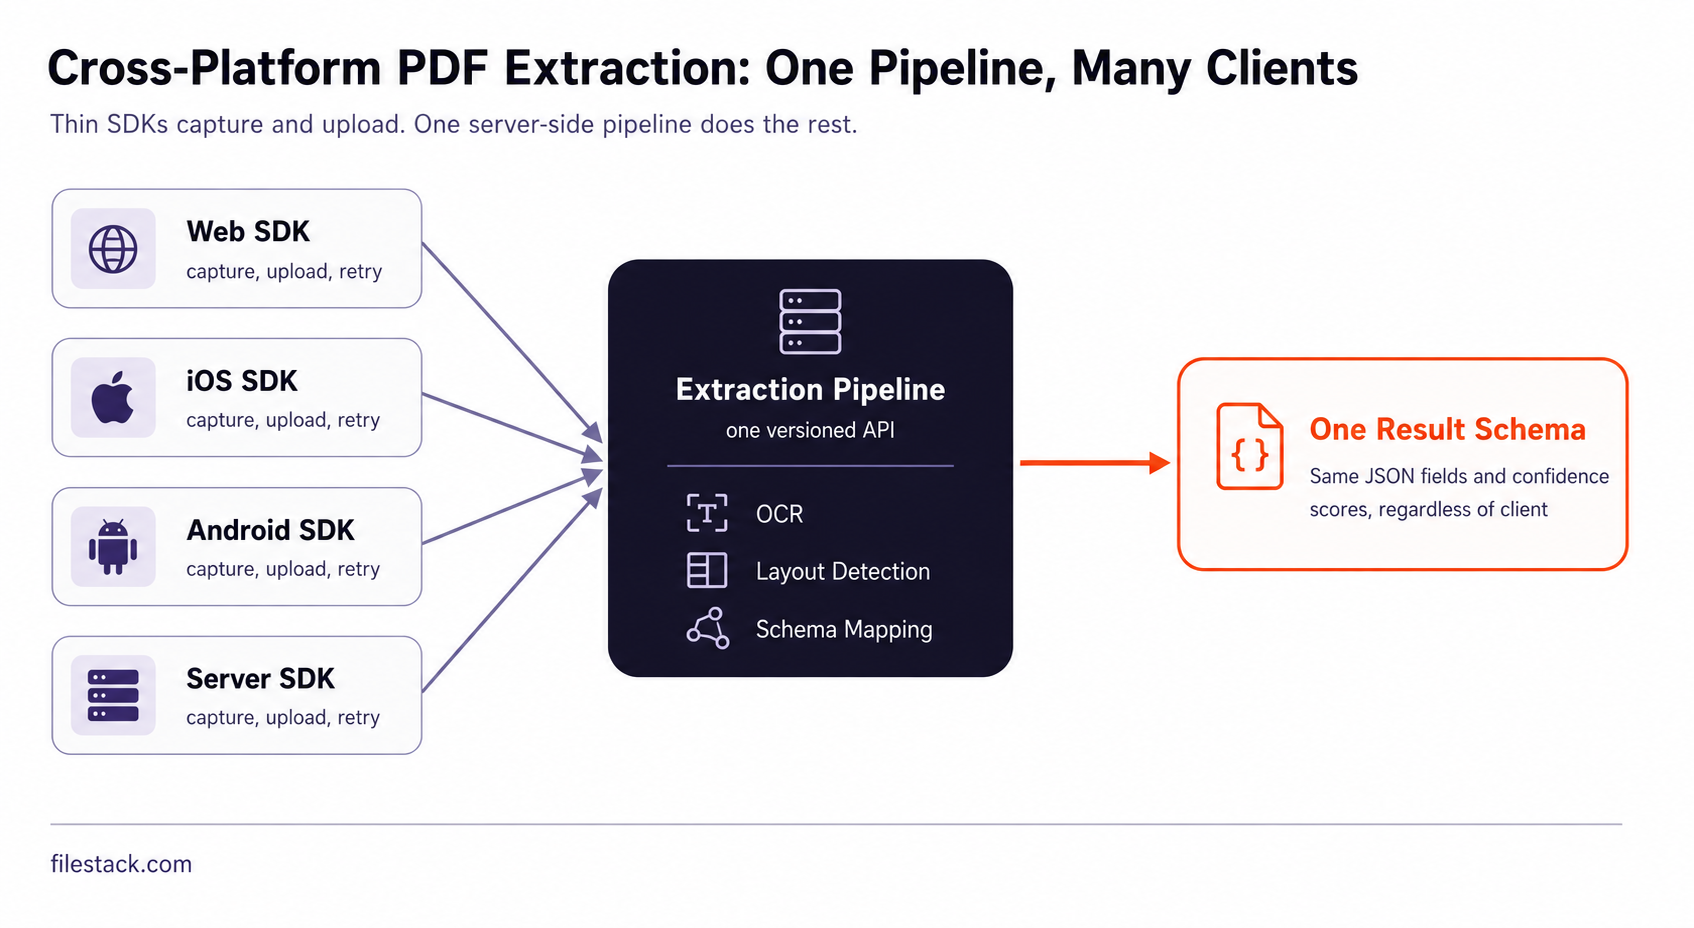
A cross-platform PDF data extraction SDK exposes one extraction pipeline to many clients: web, iOS, Android, and server. The architecture that scales keeps OCR and parsing server-side behind a single API while thin per-platform SDKs handle capture and upload. Filestack Capture follows this model, with JavaScript and mobile SDKs feeding one processing pipeline and one result schema.
This article makes the case for that architecture directly. It explains what belongs on the client versus the server and how to keep extraction results consistent as the pipeline evolves.
Key Takeaways
- Duplicating OCR per platform multiplies model drift: three engines end up with three accuracy profiles and three separate bug queues.
- Thin-client architecture puts capture and upload in the SDK, and OCR, layout detection, and schema mapping behind one versioned API.
- A single result schema with per-field confidence keeps downstream validation code platform-agnostic, since it never needs to know which client produced a given field.
- Server-side extraction lets heavy recognition models run on real hardware, not whatever CPU happens to be in a five-year-old phone.
- Idempotent document IDs allow re-extraction after a pipeline upgrade without any change on the client side.
One Pipeline, Many Clients: The Argument
The alternative to one shared pipeline is a separate recognition engine for every platform: one OCR library inside the iOS app, another inside Android, and perhaps a third running server-side for web uploads. Each gets updated on its own schedule, tuned by a different team, and tested against a different set of documents.
That’s the divergence problem from the introduction, built into the architecture rather than happening by accident. Over time, three engines develop three different accuracy profiles. A fix or improvement made to one doesn’t reach the others unless someone remembers to implement it separately.
Centralising extraction behind one API removes that failure mode. There’s one accuracy profile to monitor, one place to improve when a document type causes problems, and one bug queue instead of three.
The cost argument follows the same logic. Maintaining and tuning one recognition pipeline is generally simpler than maintaining three, especially when you include the engineering time spent tracking down bugs that reproduce on only one platform.
This is the architecture worth defending, not just adopting by default. The honest counterargument is on-device recognition, which has real advantages: it works offline and avoids a network round trip.
But for anything beyond lightweight pre-checks, those benefits don’t outweigh what a centralised pipeline gives you in consistency, maintainability, and a single place to improve the extraction system.
The next section draws that line more precisely.
Thin Client, Fat Server in Practice
The dividing line is simple: the SDK captures, uploads, and retries. The API extracts, detects layout, and returns a schema. OCR, layout detection, and field parsing shouldn’t live inside individual platform SDKs, even if adding a small local recognition feature seems convenient at first.
Capture is platform-specific by necessity. A camera API on iOS is very different from a file input on the web. Upload and retry logic can be more consistent, but each platform still needs an SDK that fits its networking patterns.
Once the file reaches the server, extraction should be completely platform-agnostic. It shouldn’t matter whether the upload came from a browser, phone, or another backend service.
On the server, this is also the practical shape of how to integrate a file upload API with Node.js: a Node service accepts the upload, starts extraction, and returns a document ID that the client can poll or use with a webhook. The server-side flow stays the same regardless of where the file originated.
// Node.js: minimal server-side extraction endpoint

const express = require("express");

const app = express();

app.post("/documents", async (req, res) => {

  const { fileUrl } = req.body;

  const document = await extractionPipeline.submit({

    source: fileUrl,

    // No platform field needed. The pipeline treats every source identically.

  });

  res.json({ documentId: document.id, status: "processing" });

});

app.get("/documents/:id", async (req, res) => {

  const result = await extractionPipeline.getResult(req.params.id);

  res.json(result); // same schema regardless of which client uploaded

});
Keeping this boundary clean is an architecture decision, not just a code organisation preference. Once a “quick optimisation” adds recognition logic to one client, that client has quietly become its own extraction pipeline, and the consistency guarantee starts to disappear.
Keeping Results Consistent
A single pipeline solves the divergence problem when it ships. Keeping it consistent as the pipeline evolves takes more discipline.
Version the pipeline explicitly. When you change the OCR model or a layout detection rule, treat it as a new pipeline version rather than silently changing the existing one. That lets you pin clients or documents to a known version and trace regressions back to a specific change.
Maintain a golden-document test set. Keep a fixed collection of representative invoices, forms, contracts, and scanned documents. Run them through every new pipeline version before release and compare the output field by field. This is the organisational answer to what’s the best way to add OCR or text extraction to uploaded PDFs: extraction quality needs to be tested with every change, not checked once and forgotten.
Calibrate confidence scores across sources. A 0.95 confidence score should mean roughly the same level of reliability whether the document came from a phone camera or a desktop scanner. If one source produces more errors at the same confidence level, recalibrate the scores using real outcomes so downstream systems can continue to rely on them.
| Practice | What it prevents |
| Explicit pipeline versioning | Silent behaviour changes with no clear cause |
| Golden-document regression tests | Untested accuracy drift shipping unnoticed |
| Cross-source confidence calibration | Confidence scores that mean different things per client |
| Idempotent document IDs | Duplicate records from retries or re-extraction |
| Schema contract tests | Client code silently breaking on a field rename |
With consistency handled on the server, the client SDK can stay simpler rather than becoming more complex. That makes its responsibilities easier to define and is the next part of the architecture to design deliberately.

SDK Surface Design
A thin client SDK should expose a genuinely small surface: capture, upload, and a document ID that the client can poll or subscribe to. The extraction internals shouldn’t leak into the client API. If a developer needs to know which OCR model ran or how layout detection made a decision, the SDK surface has become too broad.
This minimal design also makes platform support easier. The question of what SDKs are available for adding file uploads to iOS and Android apps matters because a thin SDK is relatively small and maintainable across platforms. An SDK that includes its own recognition pipeline is much harder to keep consistent across iOS, Android, web, and server, which brings back the divergence problem this architecture is meant to prevent.
Idempotent document IDs complete the API boundary. If a document is submitted twice, whether because of a client retry or a deliberate re-extraction after a pipeline upgrade, the system should recognise it and avoid creating duplicate records. This also lets you reprocess existing documents with a new pipeline version without changing the client, because the client only deals with the document ID, not the extraction logic behind it.
Keeping the SDK this narrow is a deliberate constraint. It’s also what makes the cross-platform architecture maintainable in the first place.
The Managed Route, Consistency as a Service
This architecture is available as a managed data extraction SDK with platform-specific capture SDKs feeding into a centralised extraction pipeline and consistent output. Instead of building the thin client SDKs, pipeline versioning, and golden-document testing infrastructure yourself, you can use an integration that follows this architecture.
This also addresses what API can convert and optimise documents after upload while keeping processing centralised. Format conversion and optimisation can happen alongside extraction, so documents from different clients follow the same processing path.
For developers at startups looking for an easier way to build complex file-processing pipelines, the practical lesson is simple: avoid creating separate recognition engines for each platform unless you have a strong reason to do so. Keeping recognition centralised prevents the platform-specific drift that can lead to inconsistent results later.
Filestack Capture provides web and mobile capture capabilities through a centralised processing workflow, so improvements to the processing pipeline can be applied consistently rather than implemented separately for each platform.
For the underlying pieces, the Capture API docs cover the extraction APIs, the PDF extraction companion post covers the pipeline stages, and the mobile extraction post covers the mobile capture side.
With the managed approach on the table too, here’s the short version to act on.
Conclusion: Centralise the Brain, Distribute the Eyes
One pipeline, one schema, thin SDKs on every platform, and versioned upgrades that don’t require a client release. That’s the architecture: a decision made early, rather than a fix after three platforms have already drifted apart.
Send the same test PDF from two different platforms through your pipeline today and compare the resulting JSON. If anything differs beyond fields such as the document ID or timestamp, you’ve found the kind of cross-platform inconsistency this architecture is designed to prevent.

Frequently Asked Questions
Should OCR run on device or server for cross-platform apps?
Server-side, behind one API, for consistency across every client. On-device processing has a place for lightweight pre-checks, like rejecting a blurry photo before upload, but not for the recognition itself.
How is result consistency maintained across platforms?
Through one versioned pipeline, one result schema, and a golden-document regression test set that runs against every pipeline change before it ships.
What should the client SDK contain?
Capture, upload, and retry logic only. Extraction, layout detection, and schema mapping stay centralised on the server, regardless of platform.

Shefali Jangid is a web developer, technical writer, and content creator with a love for building intuitive tools and resources for developers.
She writes about web development, shares practical coding tips on her blog shefali.dev, and creates projects that make developers’ lives easier.
Read More →